Create a Warm Tier on Data Node
When you use Graylog Data Tiering, you set data storage retention policies when you create or update index sets. In fact, you can set different tier policies for each index set, based on the requirements of the data they contain. Establishing a retention policy with a warm tier lets you maintain less-frequently searched data in lower cost and lower performance storage. See Data Tiering for complete information.
If you intend to use data tiering with a warm tier, you first need to configure your backend storage. This article explains how to prepare your environment for a warm tier on a Data Node installation, and also includes steps to follow to enable a warm tier for both new and existing index sets.
Hint: If you are using a self-managed OpenSearch installation, the requirements and procedures are different. See Create a Warm Tier on Self-Managed OpenSearch for information.
Prerequisites
Before proceeding, ensure that the following prerequisites are met:
-
You must be a Graylog administrator to set up a warm tier backend and enable a warm tier.
-
You must have appropriate credentials to configure your chosen storage backend.
Prepare Your Environment for a Warm Tier
Before you can enable a warm tier for your Data Node installation, you must set up a storage repository. We recommend that you locate your warm tier data in an S3
The initial steps for enabling a repository are completed outside of the Graylog web interface and differ depending on the storage backend you choose:
 For Amazon S3, OVH, and SysEleven, follow these steps ▼
-
In the Data Node configuration file,
datanode.conf, for all search nodes, specify the required keys:-
s3_client_default_access_key -
s3_client_default_secret_key -
s3_client_default_endpoint -
s3_client_default_region(required for OVH and SysEleven; optional for Amazon S3)
-
-
Restart all search nodes for the changes to take effect.
For Google Cloud Storage (GCS), follow these steps ▼
-
In the Data Node configuration file,
datanode.conf, for all search nodes, specify the required key:-
gcs_credentials_file
-
-
Restart all search nodes for the changes to take effect.
For an Apache Hadoop Distributed File System (HDFS), follow these steps ▼
-
In the Data Node configuration file,
datanode.conf, for all search nodes, specify the required key:-
hdfs_repository_enabled = true
-
-
Restart all search nodes for the changes to take effect.
For a local file system, follow these steps ▼
-
In the Data Node configuration file,
datanode.conf, for all nodes, specify the location of the local storage with thepath_repoproperty. This storage location must be located on shared storage that is accessible from all nodes, such as an NFS share. -
(Optional) If your architecture includes dedicated warm tier nodes, set the
node_rolesproperty indatanode.confon all nodes:-
For hot tier nodes:
Copynode_roles = cluster_manager,data,ingest,remote_cluster_client -
For warm tier nodes:
Use this role name if you're running OpenSearch 3.0 and later:
Copynode_roles = warmUse this role name if you're running a version before OpenSearch 3.0:
Copynode_roles = searchHint: Using dedicated warm tier storage is a complex architectural decision involving your data retention requirements and your search volume and search range needs. Typically, this option is used only in larger environments. If you implement warm tier with mixed role nodes, you don't need to set
node_roles. All necessary roles are assigned when you set thepath_repoproperty.
-
-
Restart all nodes for the changes to take effect.
For an Azure Blob Storage backend, follow these steps ▼
-
In the Data Node configuration file,
datanode.conf, for all search nodes, specify the required keys:-
azure_client_default_account: Sets the Azure Storage account name (required). -
azure_client_default_key: Sets the Azure Storage account key (required ifazure_client_default_sas_tokenis not set). -
azure_client_default_sas_token: Sets the Azure shared access signature token (can be used instead ofazure_client_default_key; one or the other must be set).
-
-
Restart all search nodes for the changes to take effect.
After your environment is prepared, create a storage repository on the Warm Tier Repositories page (System > Indices > Warm Tier Repositories). See Manage Warm Tier Repositories for the steps for your backend type.
Set Up a Warm Tier
When your environment is ready for Data Tiering, you can enable the warm tier for both new and existing index sets.
Enable the Warm Tier for a New Index Set
You can select warm tier for a new index set when you create it. You can create a new index set based on built-in index set templates provided by Graylog or you can create custom templates for your environment.
For complete information about creating index sets and index set templates, including how to enable the warm tier, see Index Set Templates.
Enable the Warm Tier for an Existing Index Set
To choose warm tier storage for an existing index set, follow these steps:
-
Navigate to System >Indices.
-
Click Edit for the desired index set.
-
In the Rotation and Retention section, select Data Tiering.
-
Enter the minimum and maximum number of days you want your data to be stored.
-
Select the Enable warm tier checkbox, then enter the minimum number of days to keep your data in the hot tier. The visual synchronously displays how long your data will be kept in each tier as you make your selections.
-
Select the repository you want your data stored in from the Repository dropdown. The menu includes any repositories you have created through the Warm Tier Repositories page.
-
Click Update index set.
View Data Tiering Configuration
After you have created or updated your index set, you can view configuration information as follows:
-
Navigate to System > Indices
-
Select the desired index set to view the index set overview page.
Here you can see warm displayed in the index title after the index prefix.
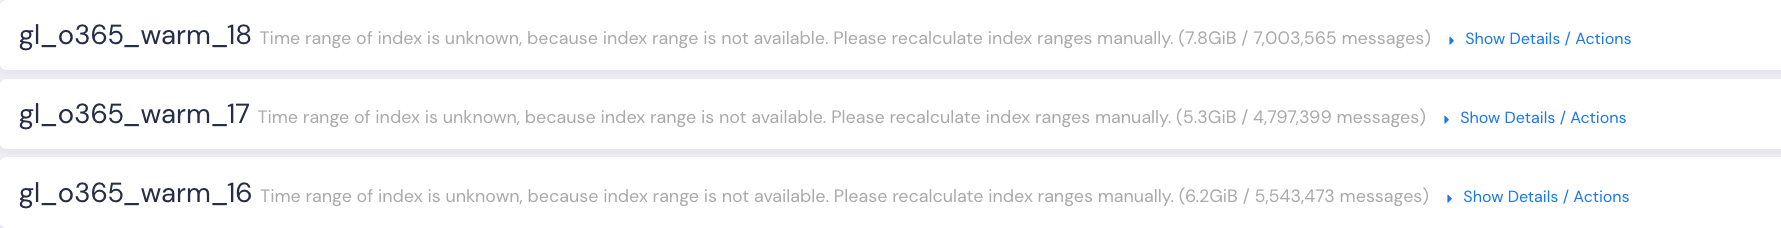
You can perform searches in the warm tier, and you can verify that your search results include the warm tier by checking the Stored in index section. You will see warm in the index set title.